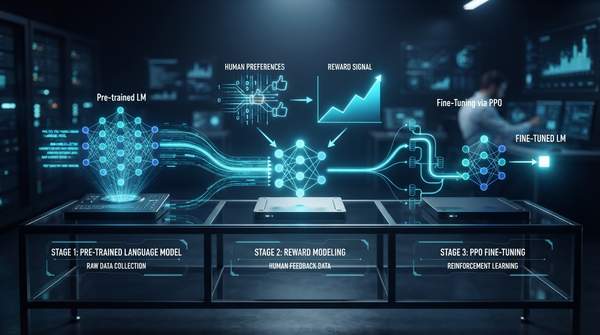
Reinforcement Learning from Human Feedback, or RLHF, is not a single training step. It is a multi-model pipeline in which a pretrained language model generates candidate responses, humans rank those responses, a separate reward model learns to score them numerically, and a reinforcement learning algorithm then uses that score to reshape the language model itself. The counterintuitive core of the method is that the humans never grade the final model directly — their judgments are distilled into an intermediate model that can hand out rewards automatically, thousands of times, without a person in the loop.
Understanding Reinforcement Learning from Human Feedback (RLHF)
RLHF exists to solve a problem that conventional machine learning objectives handle badly: many desirable behaviors are subjective or hard to quantify. As Zhaolin Gao of Carnegie Mellon University's Machine Learning Department explains in a technical tutorial, RLHF aligns AI systems with human preferences by training them on feedback from people rather than predefined reward functions, because manually coding every desirable behavior is often infeasible for complex tasks. It matters most where success is hard to define — generating helpful and safe text responses being the canonical example.
The technique's deceptive difficulty comes from its architecture. Nathan Lambert and colleagues at Hugging Face, in an early and widely cited walkthrough of the method, describe RLHF as "a challenging concept because it involves a multiple-model training process and different stages of deployment." They break it into three core steps: starting from a pretrained language model, gathering data and training a reward model, and fine-tuning the language model with reinforcement learning. Each stage produces a distinct artifact — a tuned starting model, a scoring model, and finally an aligned policy — and confusing those artifacts is the most common conceptual error.
Learning from human preferences is also older than the current wave of chatbots. Chip Huyen notes that the approach has been around for over a decade, with OpenAI exploring it back when its main bet was robotics. What changed is scale: the same preference-learning machinery now sits on top of models pretrained on enormous corpora.
Stage 1: Supervised Fine-Tuning and Human Preference Data Collection
The pipeline begins with a language model that has already been pretrained with classical objectives — next-token prediction over massive text corpora. Pretraining is by far the most expensive phase; Huyen cites the InstructGPT model as an example, where pretraining consumed roughly 98 percent of overall compute and data resources. Fine-tuning stages, in this framing, unlock capabilities the pretrained model already has but that users cannot reliably reach through prompting alone.
Before any reinforcement learning happens, the model typically undergoes supervised fine-tuning (SFT): it is trained on high-quality prompt-response pairs, often written or curated by humans, so it can follow instructions in the first place. AWS's explainer of the technique describes this as fine-tuning a commercial pretrained model so its responses to predetermined prompts can be compared against human responses collected beforehand.
SFT is not strictly mandatory — Huyen points out that you can run RLHF directly on top of the pretrained model, skipping the SFT phase. Empirically, however, combining all three steps gives the best performance. Once the SFT model exists, it is used to generate multiple candidate responses to the same prompt, and human labelers compare those outputs — typically ranking them or selecting which of a pair is better. These comparisons, not absolute grades, are the raw material for the next stage.